


CapEx Runs. Revenue Waits
Every month without go-live means hardware depreciation, power contracts, and operations costs run in full while GPU revenue stays at zero. In an AI infrastructure CapEx model, delay has a precise financial cost per day.
 Wistron AIDC Total Solution
Outcome-driven AI infrastructure
Wistron AIDC Total Solution (WATS) delivers enterprise-grade AI GPU infrastructure in 2-3 months, starting from your requirements and matched with the best-fit software platform, vendor-agnostic architecture, and global operations support.
Every month without go-live means hardware depreciation, power contracts, and operations costs run in full while GPU revenue stays at zero. In an AI infrastructure CapEx model, delay has a precise financial cost per day.
When compute, network, storage, software, and operations belong to separate vendors, integration becomes no one's core responsibility. Gaps turn into weeks of delay, and the business absorbs every overrun.
Without quota boundaries, chargeback data, and utilization reporting, expensive GPU capacity stays underused and unaccountable. Leadership loses the visibility needed to measure returns or justify expansion.
Enterprise and sovereign AI platforms require RBAC, tenant isolation, audit trails, and policy enforcement from day one, not retrofitted later. Skipping governance at the start means inheriting compliance debt at scale.
AI infrastructure is the production capacity behind your AI output. WATS starts from your requirements, assembles best-fit GPU compute, networking, storage, and support, and delivers it as a managed, governed AI cloud service. Chthonia provides the operations control plane. One team accountable from design to day-one operations.


AIDC connects architecture planning, Chthonia software, validated infrastructure, global logistics, and ongoing support into one accountable delivery model.
Chthonia turns multi-IDC GPU infrastructure into an AI cloud service that is self-service, governed, observable, billable, and optimizable. It is not a GPU IaaS layer, a monitoring tool, or a billing system. Chthonia connects GPU infrastructure, AIDC operations, AI platform teams, SRE, FinOps, and the customer portal into one governed layer, transforming raw GPU resources into enterprise-operable AI cloud service.
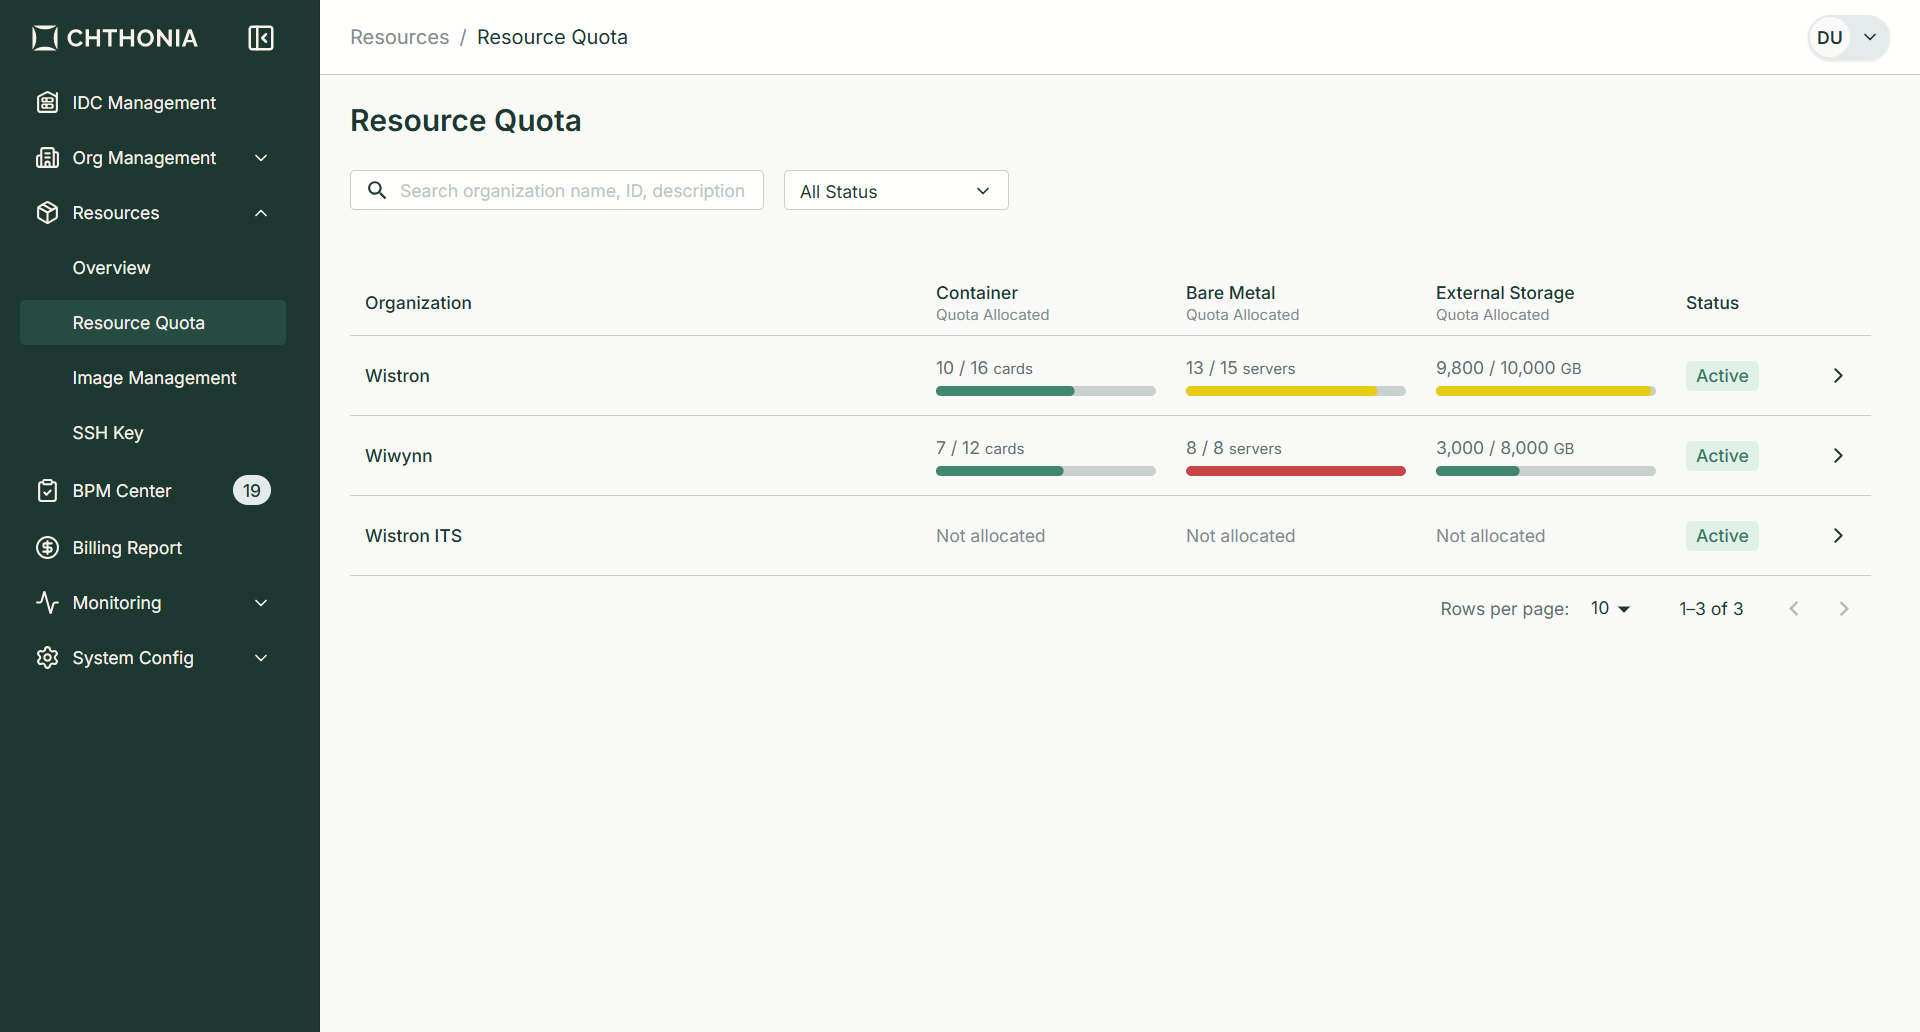
Bare metal and container provisioning with multi-tenant governance, quota controls, scheduling policies, and full service portal visibility.
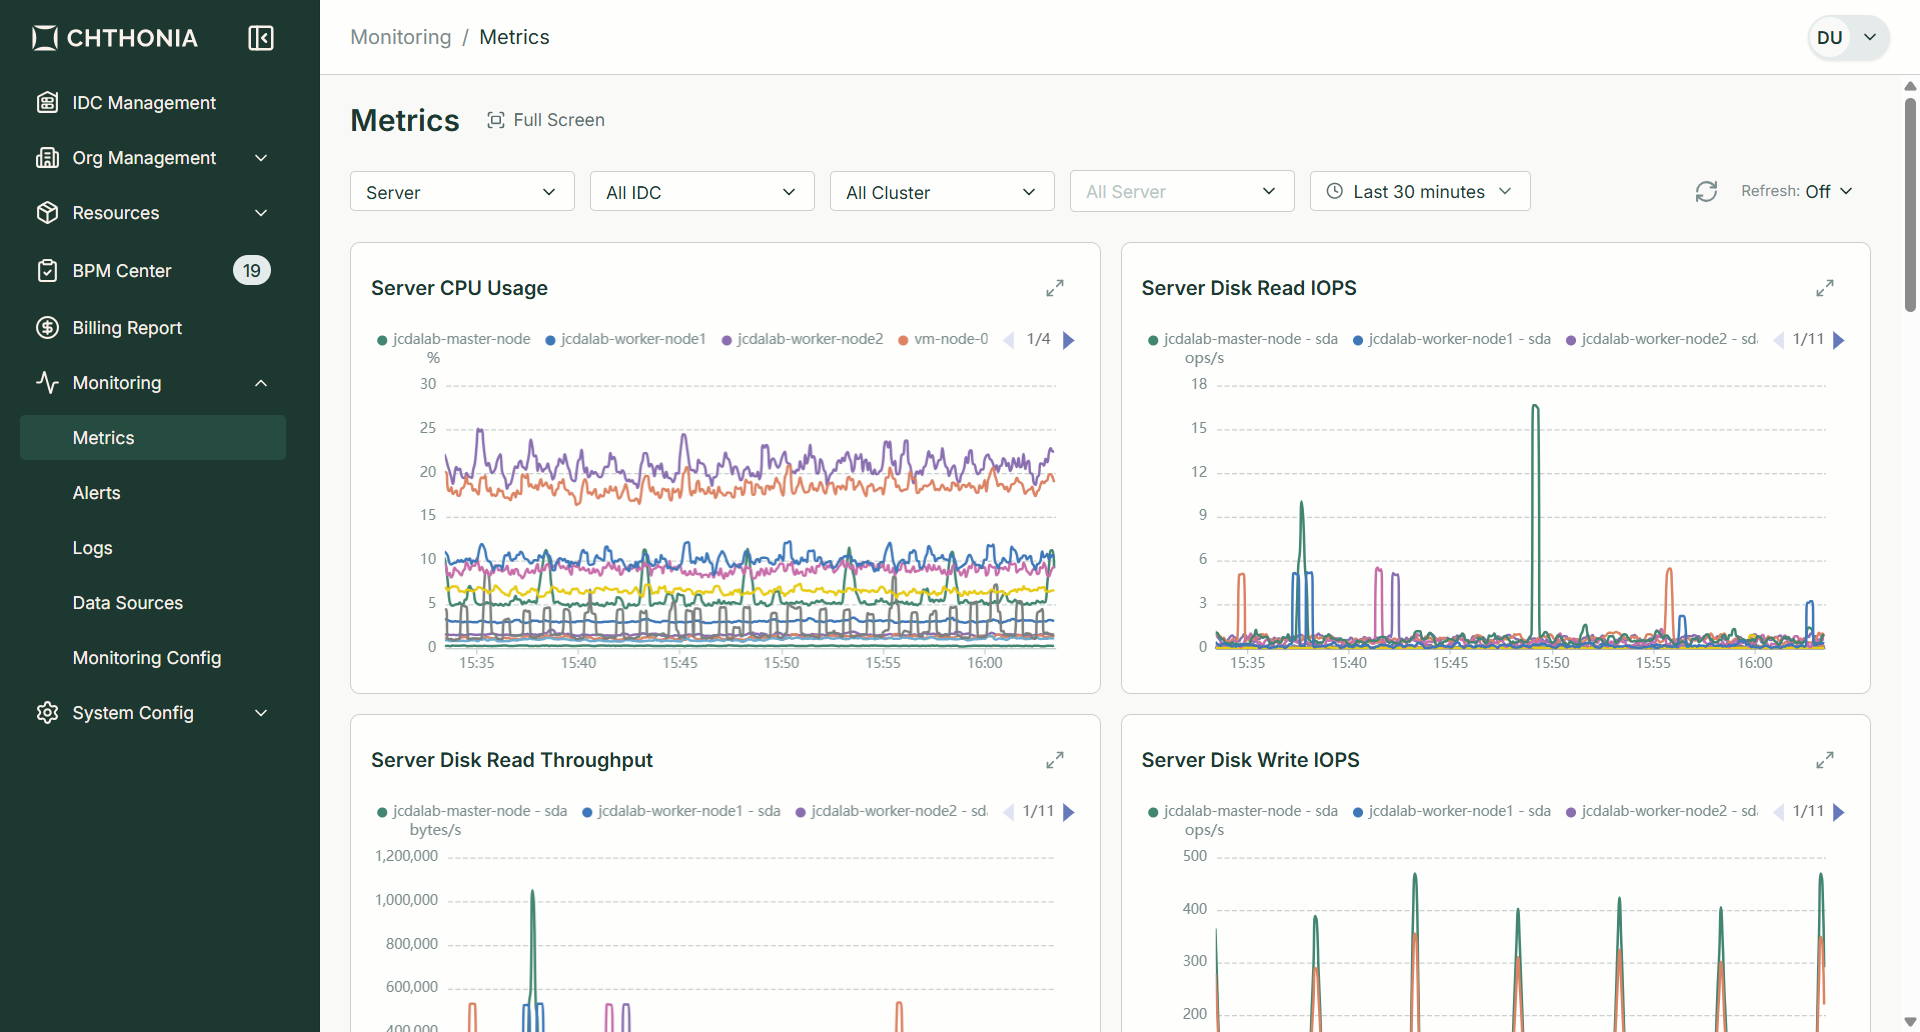
Monitoring, alerting, incident workflows, and SLA management purpose-built for teams running mission-critical GPU infrastructure.
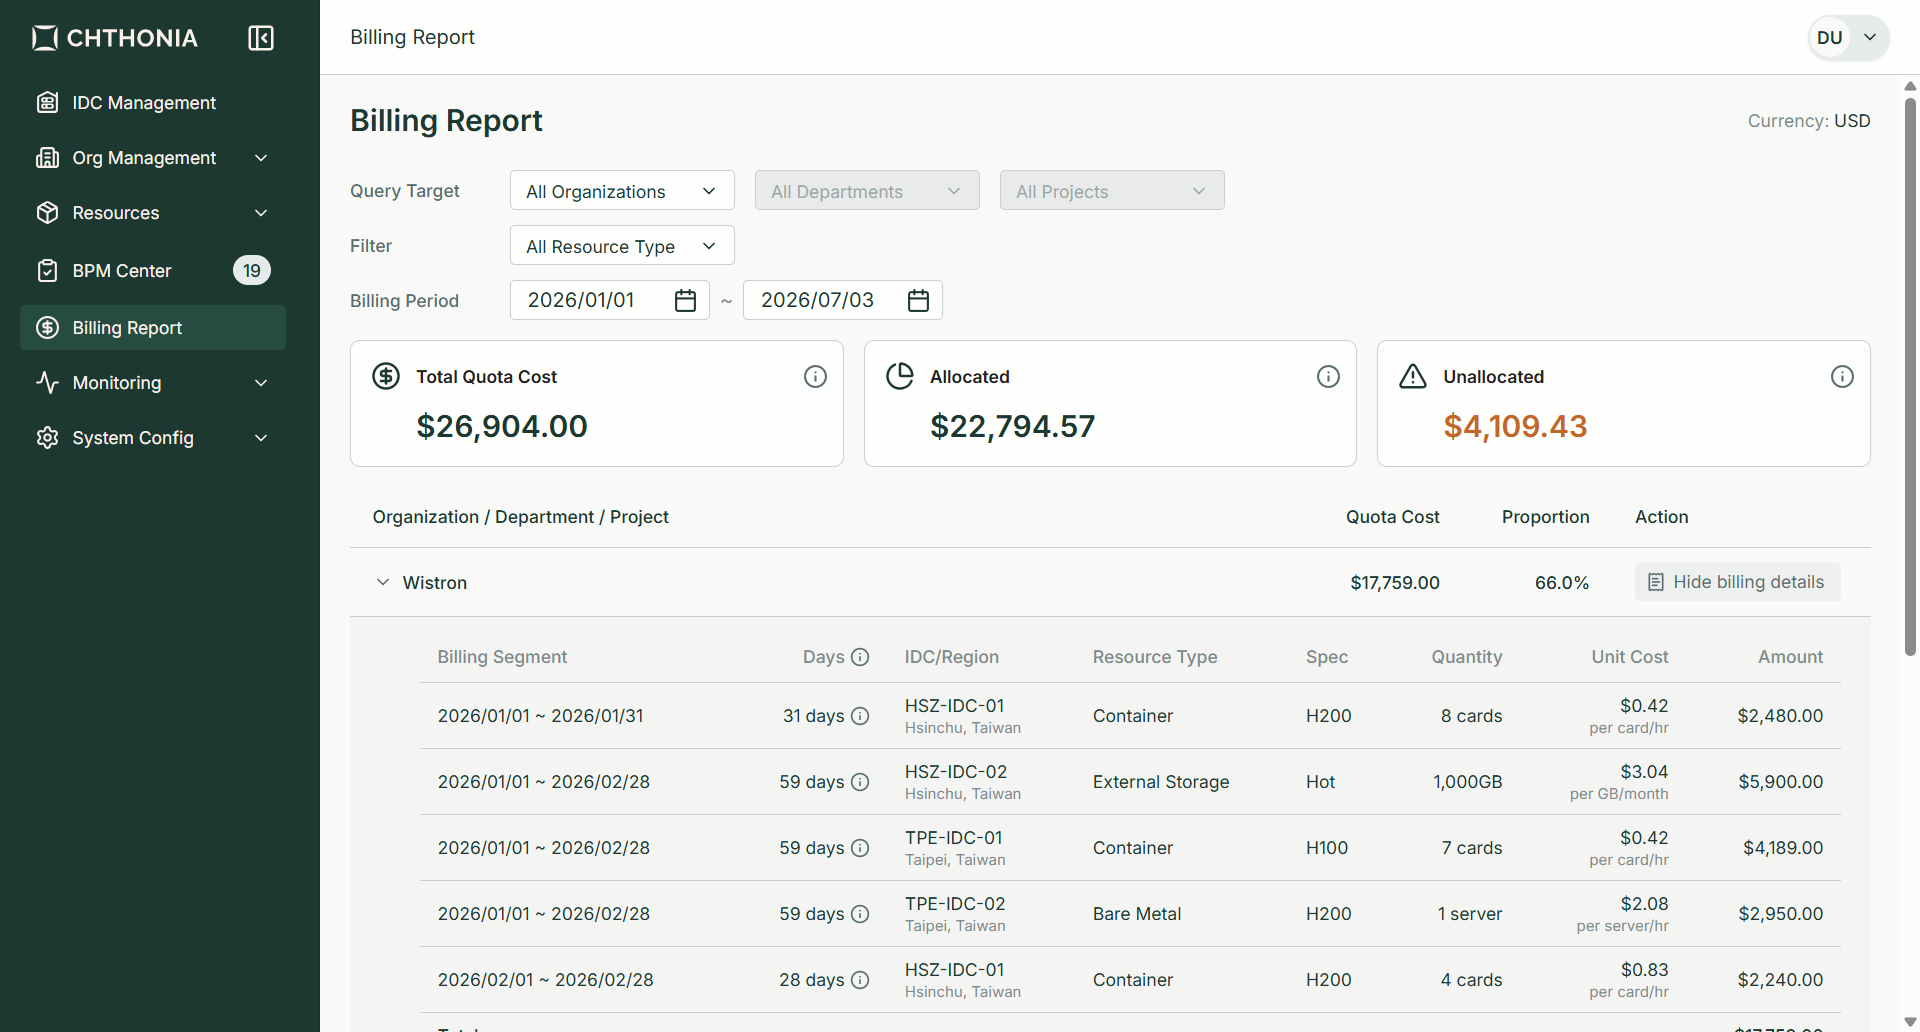
Asset lifecycle tracking, cost visibility by org and project, and chargeback-ready reporting that gives leadership the transparency to govern AI capacity.
AIDC architecture, rack layout, cabling, network fabric, and deployment model.
GPU compute, networking, storage, optics, cables, and global logistics coordination.
On-site implementation, system integration, Chthonia deployment, and acceptance validation.
Monitoring, incident response, help desk, on-site maintenance, and service reporting.
Utilization analysis, capacity planning, policy tuning, and continuous product upgrades.
Build a private AI factory with data sovereignty, enterprise governance, and predictable GPU operations.
Launch a multi-tenant GPU cloud service faster with IaaS workflows, quota boundaries, and service management.
Deploy regulated AI infrastructure with isolation, auditability, local control, and multi-region expansion paths.
We are a team of AI infrastructure engineers, cloud architects, and global operations specialists. Our mission is to turn AI infrastructure investment into operational, governed AI capacity. Faster to deploy. Easier to govern. Built to scale.
Built on an outcome-driven philosophy, we start from each customer's requirements and deliver GPU capacity as a managed AI cloud service. Chthonia provides the operations control plane. Our end-to-end services work with any hardware, any cloud model, and any scale.
Tell us your target GPU capacity and timeline. We will propose a reference architecture and practical path to production.
