AI Factory
Input: power + GPUs. Data centers manufacture intelligence, not just host applications.
 Wistron AIDC Total Solution

Chthonia turns multi-IDC GPU infrastructure into an AI Factory Operating Platform: the enterprise control plane that makes GPU capacity self-service, governed, observable, billable, and optimizable. It connects GPU infrastructure, AIDC operations, AI platform teams, SRE, and FinOps into one layer that turns raw compute into revenue-aware AI production capacity.
The economics
Jensen Huang's COMPUTEX framing is now an operating reality. A data center no longer just hosts applications; it manufactures intelligence. Power and GPUs go in; tokens come out. Throughput, uptime, and performance-per-watt become financial levers.
Input: power + GPUs. Data centers manufacture intelligence, not just host applications.
The production unit: training, inference, and agents are measured and monetized in tokens.
KPIs shift to tokens/sec and tokens/watt; throughput and efficiency per watt become financial levers.
Operate compute like a revenue-generating production line: more tokens at a lower cost per token.
The operations gap
In a CapEx-heavy AI factory, every week without an operating layer is depreciation, power, and idle capacity running at full cost while token output stays at zero.
Chthonia closes the gap between raw GPU capacity and a revenue-operating AI factory.
GPU supply fragmentation and long onboarding cycles mean capacity sits idle while teams wait.
Multi-DC, multi-cluster GPU, network, and storage dependencies slow incident response and recovery.
Idle GPUs from weak quota controls, no chargeback model, and no way to prove ROI per token.
Tenant isolation, RBAC, and audit must be standardized from day one, not retrofitted later.
What Chthonia is
An enterprise platform that turns GPU infrastructure into governed, observable, resilient, and revenue-aware AI production capacity. Chthonia is not just IaaS. Not just monitoring. Not just billing. It connects all three into a revenue-operating control plane.
The operating loop
One closed-loop workflow from capacity planning to token economics. Every stage feeds the next.
Capacity forecast and AI-agent recommendations.
Tenant / project quotas and IB VPC policy.
Container / bare-metal scheduling and resilience.
Tokens/sec, GPU utilization, NVLink / RDMA health.
Cost/token, chargeback, and ROI improvements.
Governed compute = monetizable AI production capacity.
Platform capabilities
The economics and operating loop above run on three productized capability modules, delivered today and expanding through 2027, unified on a shared control plane with monitoring, RBAC, billing, and AIOps.
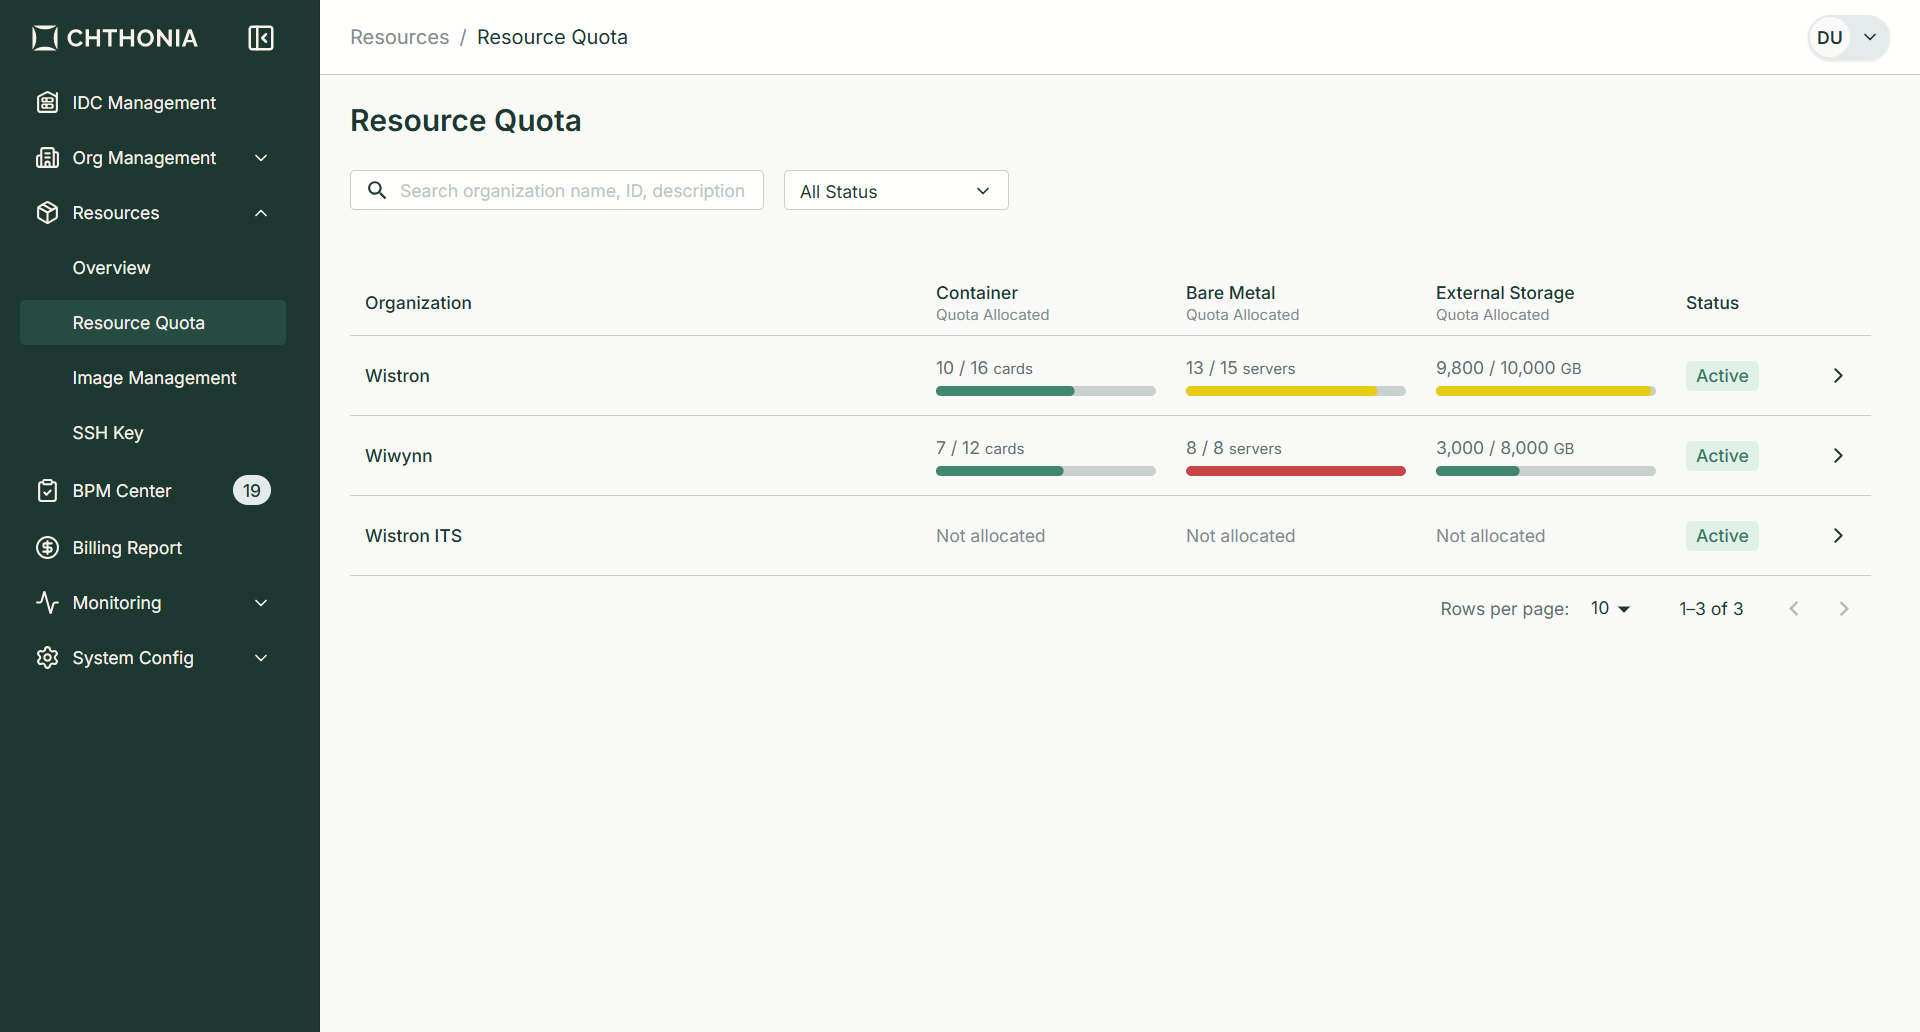
GPU bare metal and container services with organization and project governance, quota controls, and service portal visibility. Purpose-built for AI platform teams running multi-tenant workloads.
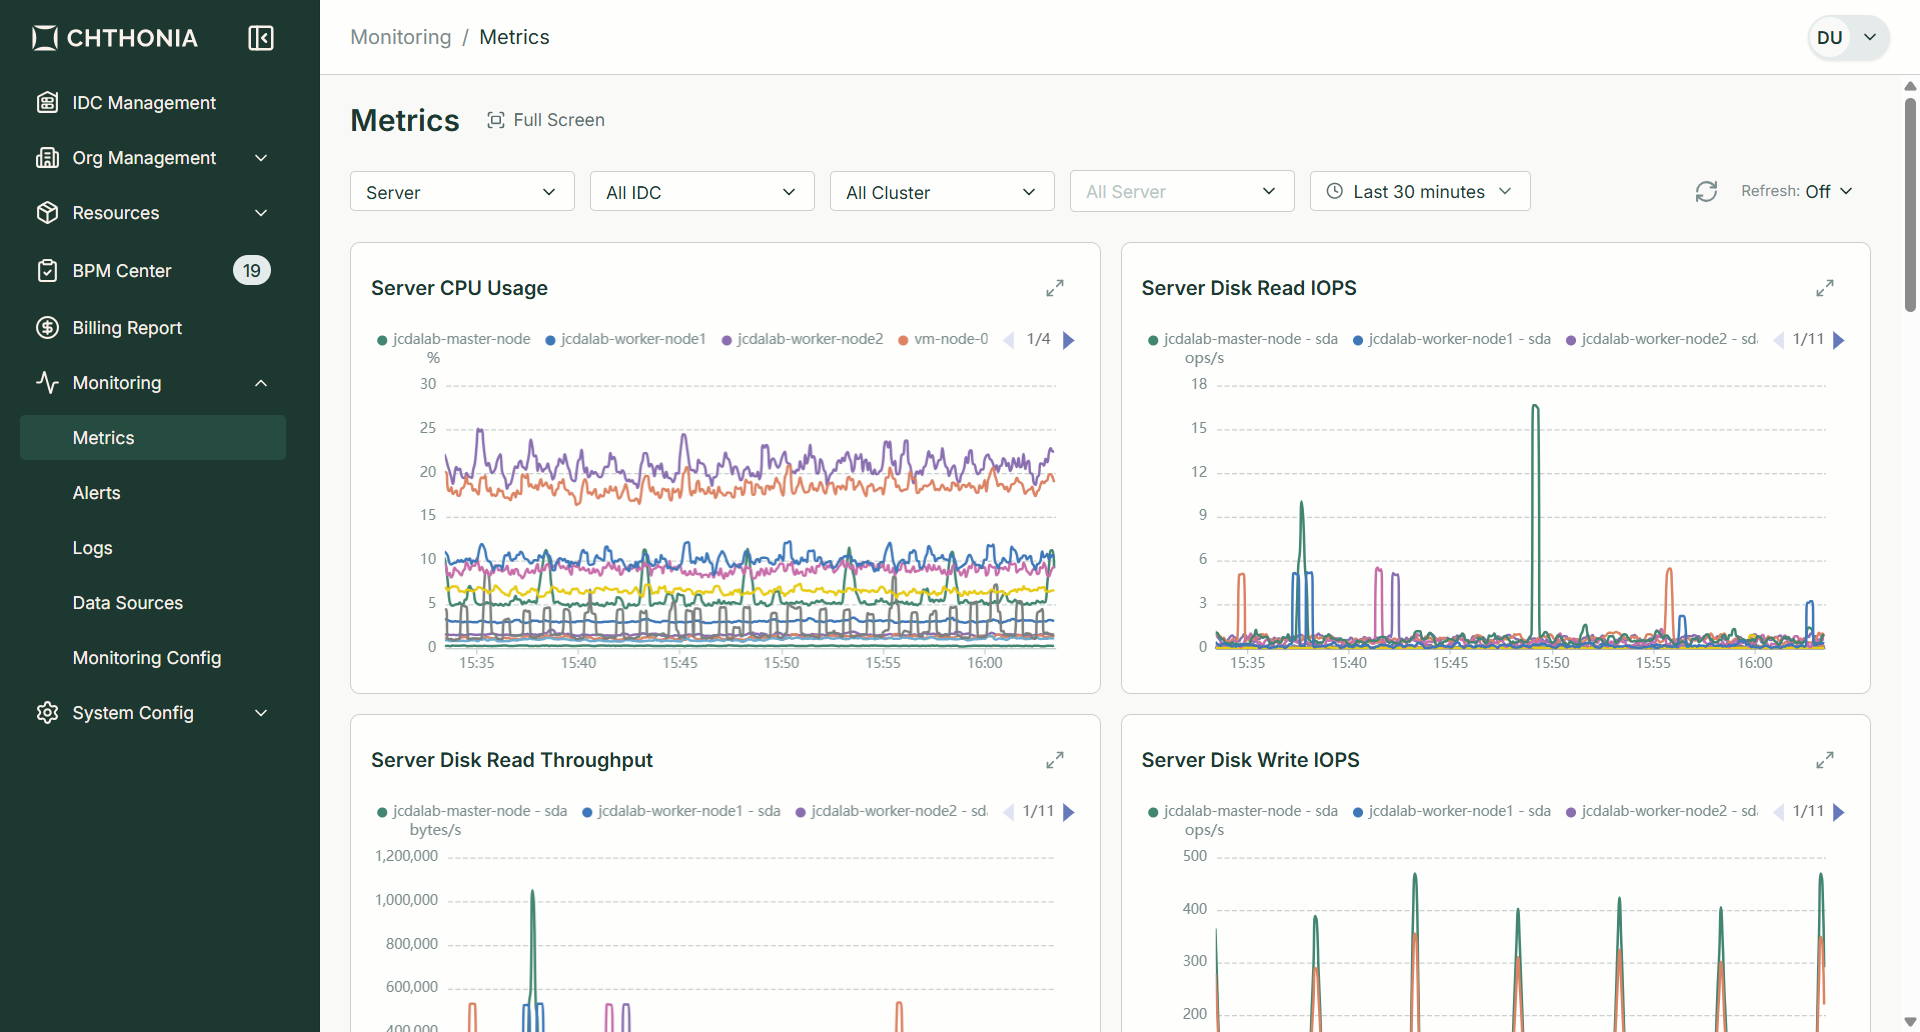
Monitoring, alerts, logs, workflow automation, help desk ownership, and SLA-ready service management. Designed for operations teams managing complex, mission-critical GPU infrastructure.
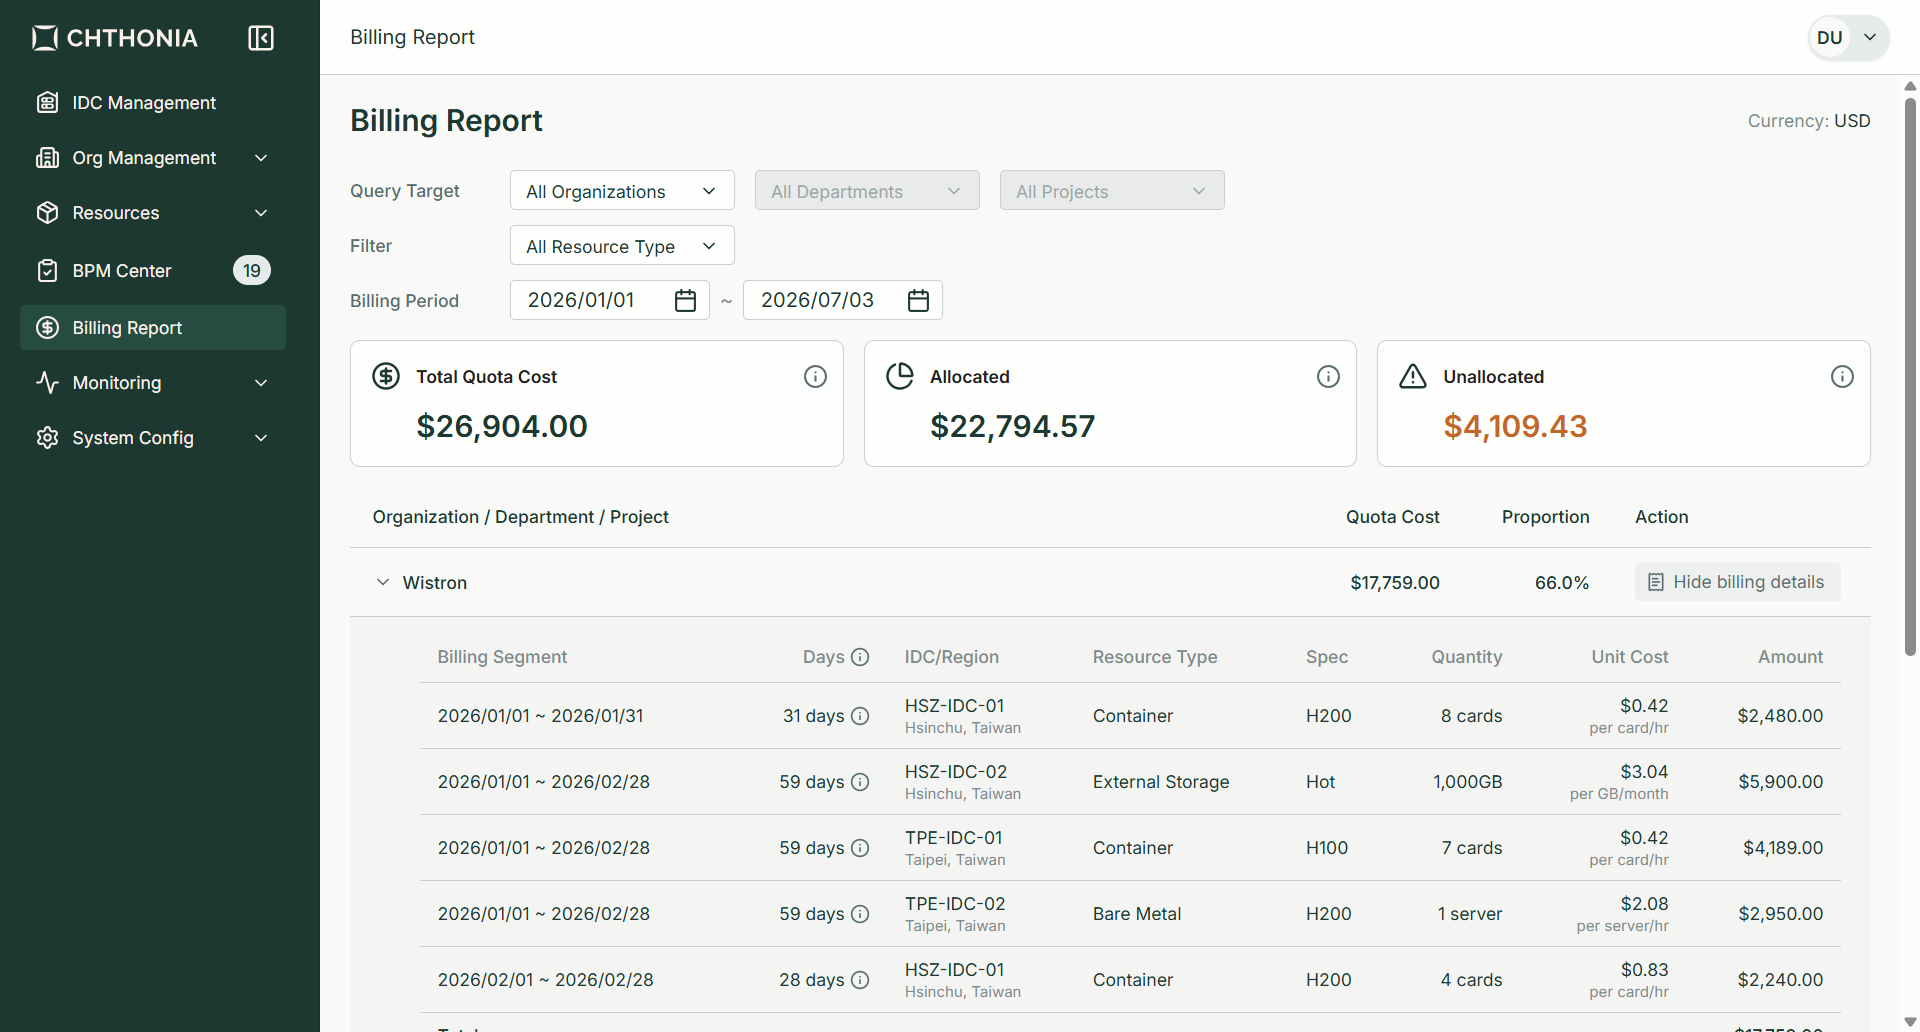
Asset lifecycle tracking, infrastructure inventory, cost visibility, chargeback-ready data, and audit-friendly controls. Gives both engineering and leadership the transparency needed to govern AI capacity.
Revenue intelligence
Chthonia translates technical telemetry into the financial language of the AI factory, so management, tenants, and operators read the same numbers.
Is cost recovered by tenant and project? Which workloads create token value? Where is revenue at risk?
Do rented GPUs fit the token budget? Is quota right-sized? Are checkpoints protecting training cost?
Tokens/sec · cost/token · GPU utilization · workload reliability · tenant margin.
Workload resilience
A runtime layer that keeps long training and inference jobs alive, and keeps GPU-hours productive, without user-side code changes.
Deploy & integrate
For enterprise AI factories, sovereign AI, and regulated data environments that require dedicated control and on-premises performance.
For GPU cloud providers and internal marketplaces that need billing, SLA management, and multi-tenant governance at scale.
For multi-site expansion, global R&D, planned burst capacity, and unified monitoring across regions and deployment boundaries.
Secure by architecture: per-tenant VPC isolation and IB VPC preserve full RDMA performance. Integrates with Kubernetes, OpenStack, observability backends, and NVIDIA NCP / SuperPOD. Full architecture, VPC, and compliance depth on the Technology page (coming).
Product roadmap
GPU cloud first, then full datacenter ops, then enterprise asset management. Each phase builds on a shared, production-grade architecture.
2026 — Available Now
2027 H1 — Coming
2027 H2 — Planned
Tell us your infrastructure scale and operational goals. We will walk you through a reference deployment and show you how Chthonia maps to your environment.
Chthonia. Powering AI from the ground up.